spdl.io.transfer_tensor_h2d
- transfer_tensor_h2d(batch: T, /, *, num_caches: int = 4) T[source]
Transfer PyTorch tensors from CPU to CUDA in a dedicated stream.
Added in version 0.7.0.
This function wraps calls to
torch.Tensor.pin_memory()andtorch.Tensor.to(), and executes them in a dedicated CUDA stream.When called in a background thread, the data transfer overlaps with the GPU computation happening in the foreground thread (such as training and inference).
See also
Multi-threading (custom) - An intended way to use this function in
Pipeline.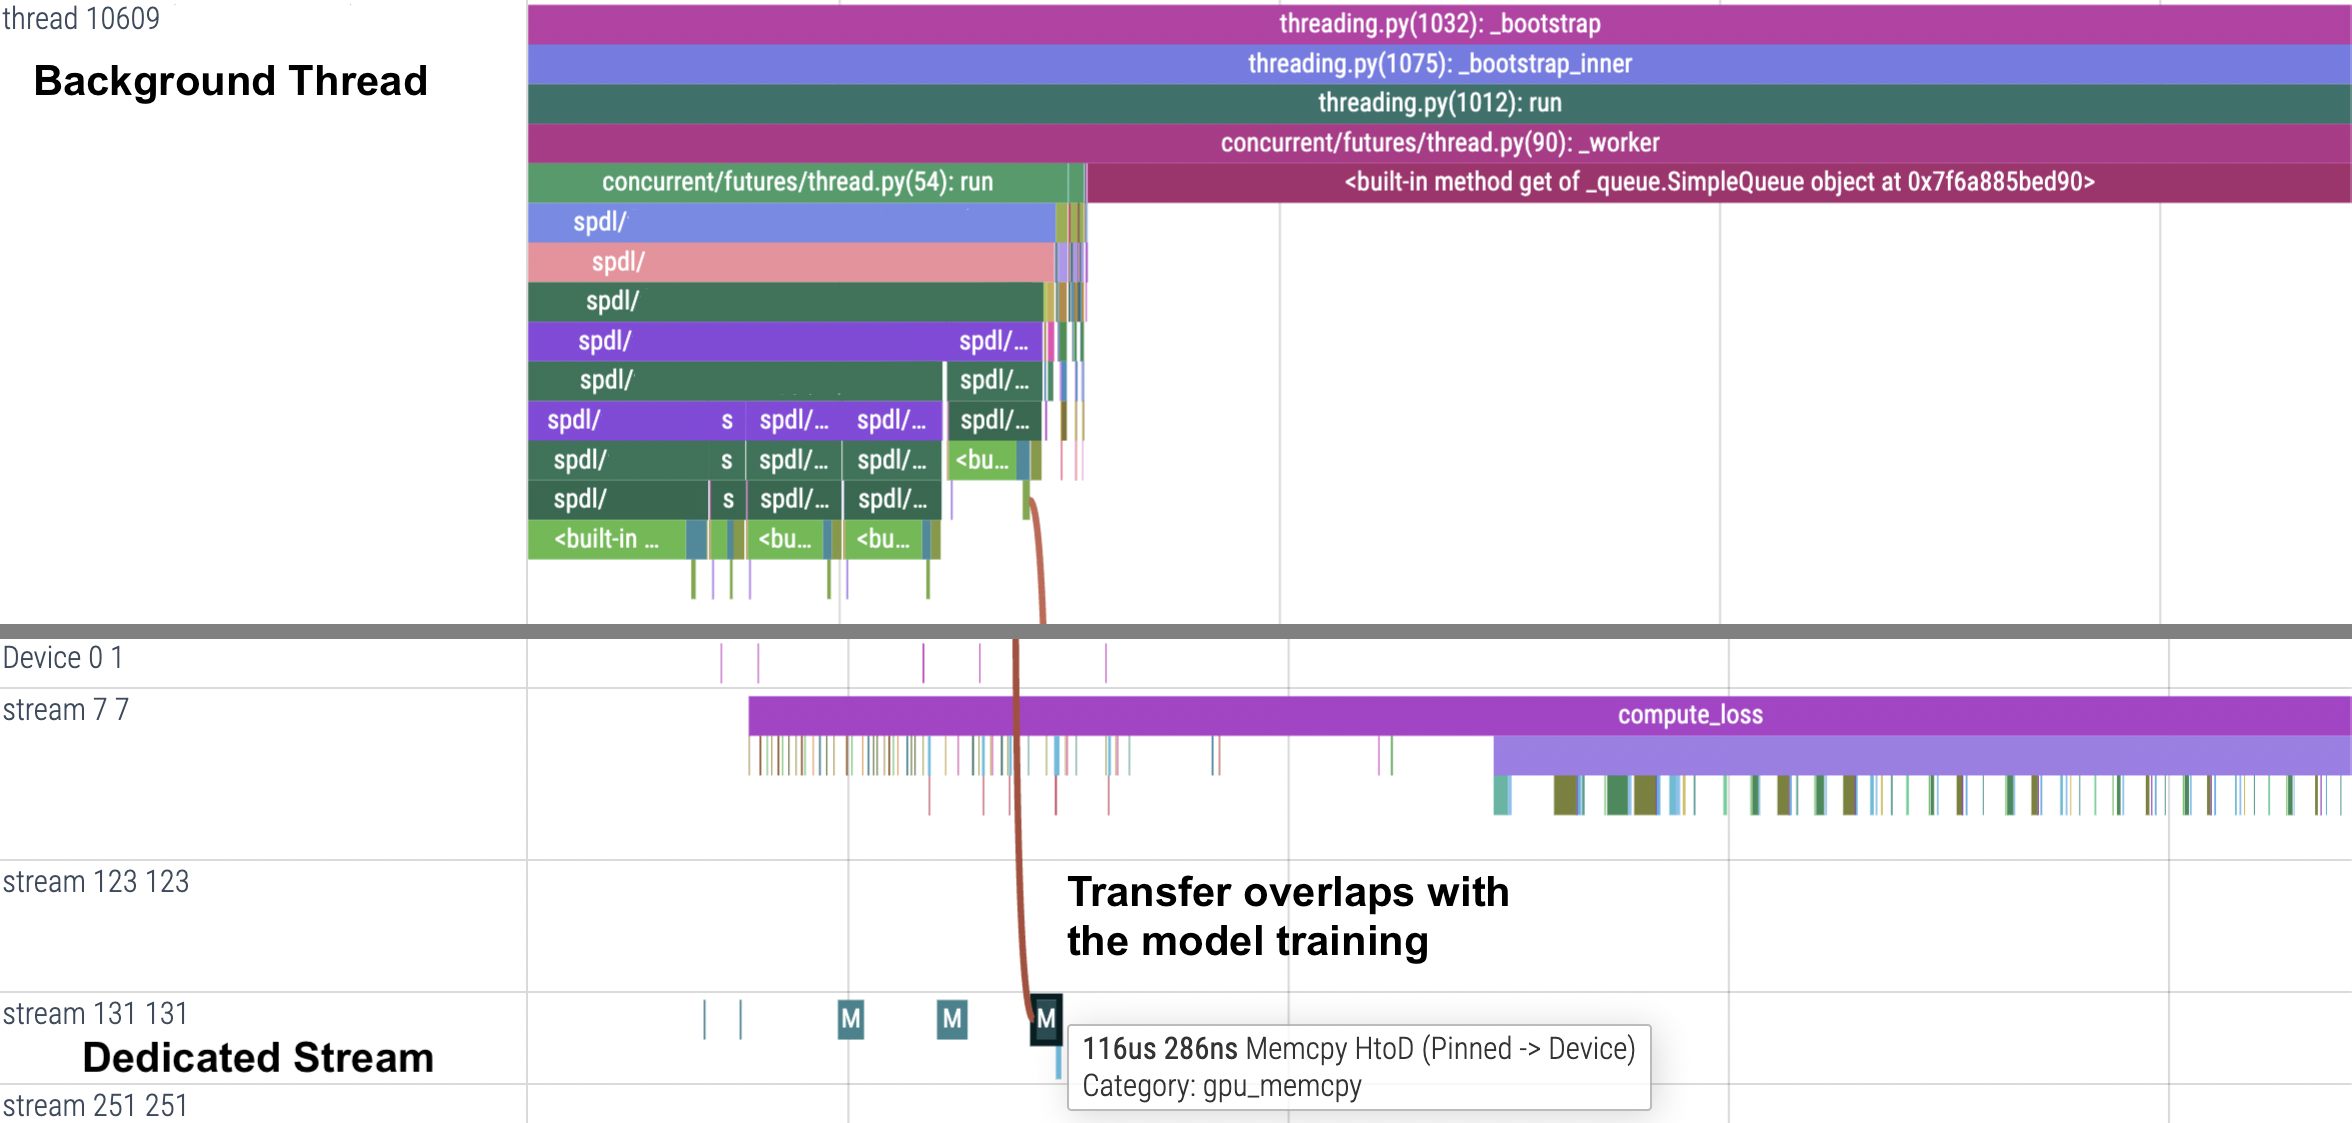
Concretely, it performs the following operations.
If a dedicated CUDA stream local to the calling thread is not found in thread-local storage, creates and caches one. (The target device is determined by the
"LOCAL_RANK"environment variable.)Activates the CUDA stream.
Traverses the given object recursively and transfers CPU tensors to CUDA. Data is first copied to page-locked memory by calling
pin_memory, then transferred to CUDA asynchronously with.to(non_blocking=True).Synchronizes the stream, to ensure that all the data transfers are completed.
- Parameters:
batch – A
torch.Tensoror a composition of tensors with container types such aslist,tuple,dictanddataclass.num_caches –
Number of batch caches to maintain the reference to. This parameter helps mitigate race conditions when using multi-threading with multiple CUDA streams.
See PyTorch CUDA Race Condition in Multi-threading for details on the rationale behind this parameter.
- Returns:
An object of the same type as the input, but the PyTorch tensors are transferred to CUDA device.
Example
from concurrent.futures import ThreadPoolExecutor

from spdl.io import transfer_tensor_h2d

with ThreadPoolExecutor(max_workers=1) as executor:
    future = executor.submit(transfer_tensor_h2d, cpu_batch)
    cuda_batch = future.result()